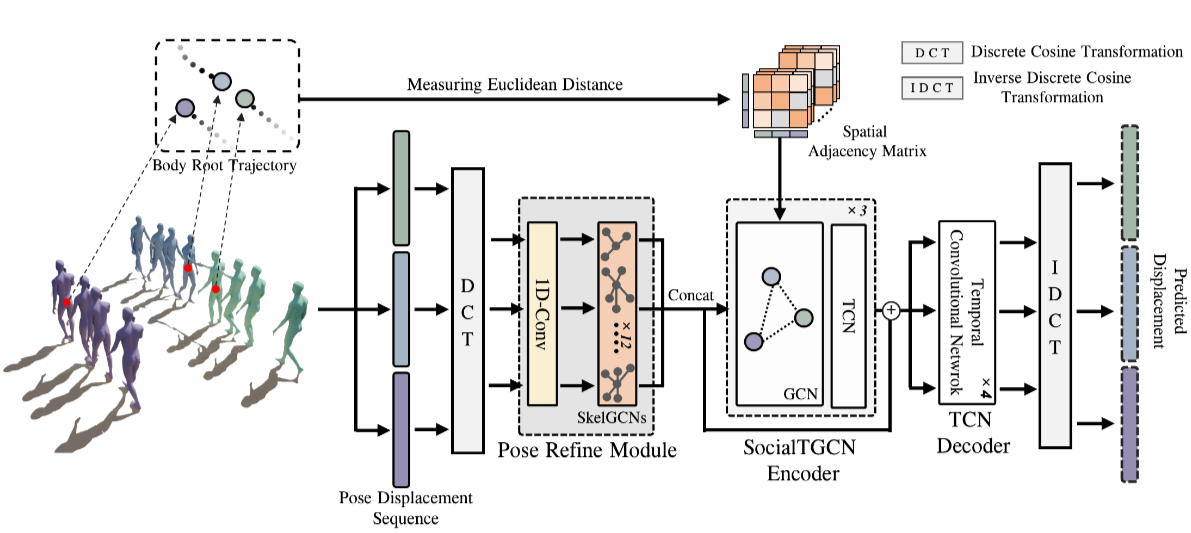
We introduce the MI-Motion dataset, a large-scale benchmark for 3D multi-person motion prediction, along with a novel baseline that achieves state-of-the-art performance.
@article{peng2026mimotion,title={The MI-Motion Dataset and Benchmark for 3D Multi-Person Motion Prediction},author={Zhou, Xiao and Peng, Xiaogang and Luo, Yikai and Wu, Zizhao},journal={Applied Soft Computing},note={Under Review},year={2026},}
Siggraph Asia
LiveDub: Real-Time Lip Sync via MambaUNet with Plug-and-Play Dental Refinement
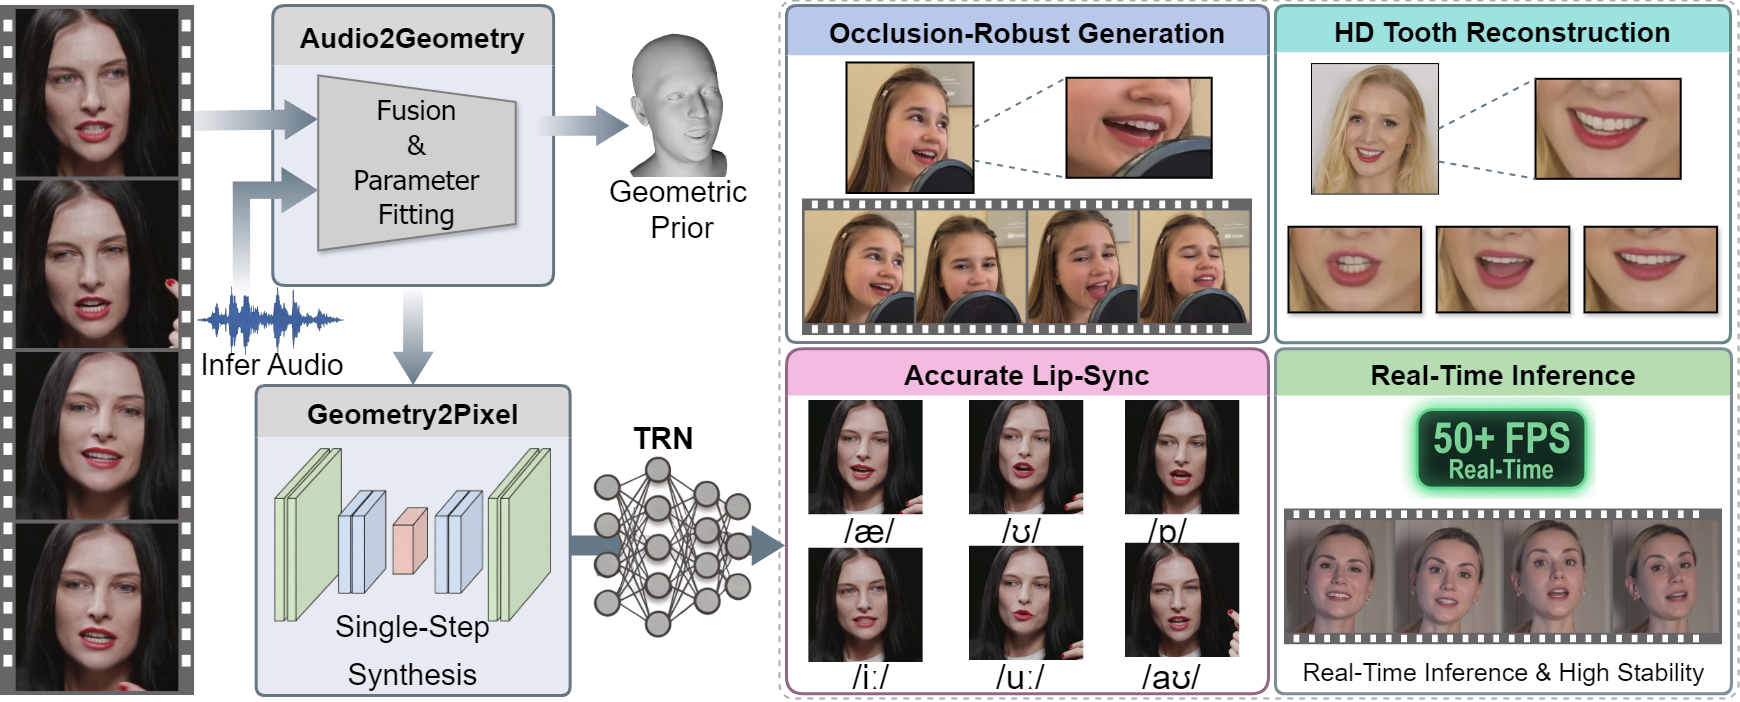
We present LiveDub, a real-time lip synchronization framework based on MambaUNet architecture with a plug-and-play dental refinement module, targeting submission to SIGGRAPH Asia 2026.
@inproceedings{zhou2026livedub,title={LiveDub: Real-Time Lip Sync via MambaUNet with Plug-and-Play Dental Refinement},author={Zhou, Xiao and others},booktitle={SIGGRAPH Asia 2026 (Under Preparation)},year={2026},note={Manuscript in preparation},}
2024
IVC
Learning Weakly Supervised Audio-Visual Violence Detection in Hyperbolic Space
Xiao Zhou, Xiaogang Peng, Hao Wen, and 4 more authors
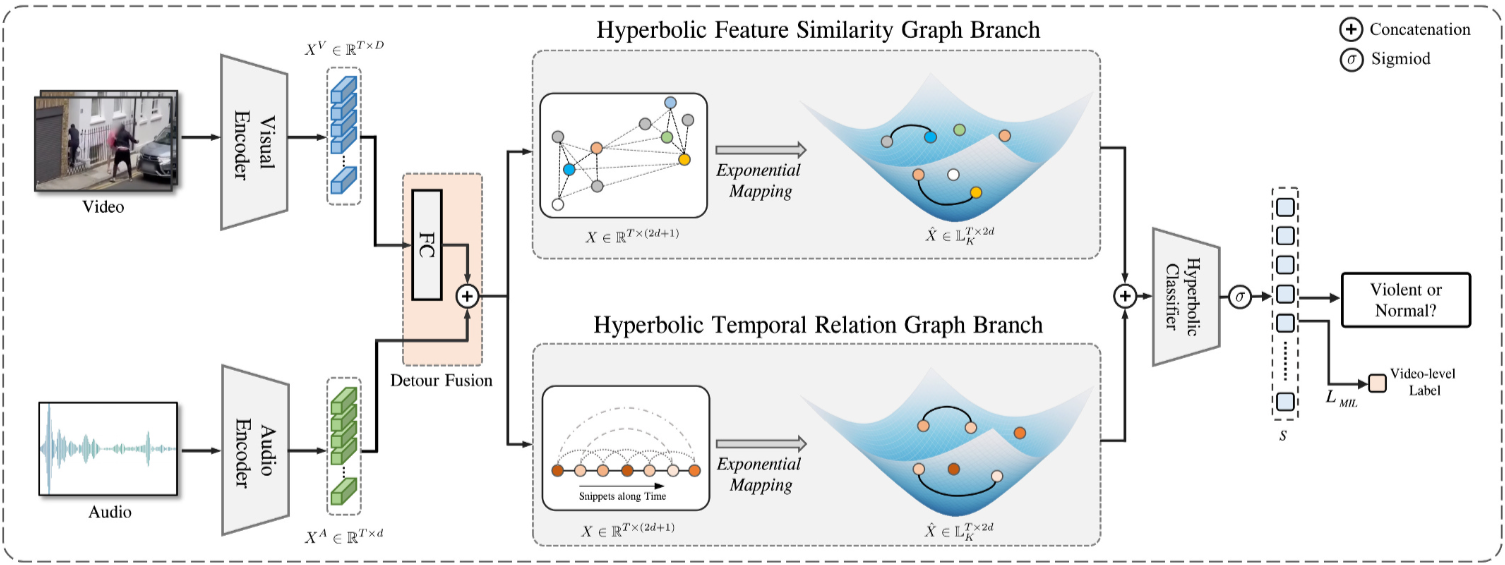
We propose a novel framework that learns snippet embeddings in hyperbolic space to improve audio-visual violence detection under weak supervision, achieving state-of-the-art performance on multiple benchmarks.
@article{zhou2024hyperVD,title={Learning Weakly Supervised Audio-Visual Violence Detection in Hyperbolic Space},author={Zhou, Xiao and Peng, Xiaogang and Wen, Hao and Luo, Yikai and Yu, Keyang and Yang, Ping and Wu, Zizhao},journal={Image and Vision Computing},volume={151},pages={105286},year={2024},month=nov,doi={10.1016/j.imavis.2024.105286},url={https://doi.org/10.1016/j.imavis.2024.105286},}