LiveDub
Real-Time Lip Sync via MambaUNet with Plug-and-Play Dental Refinement
LiveDub
Real-Time Lip Sync via MambaUNet with Plug-and-Play Dental Refinement
Anonymous Authors
Abstract
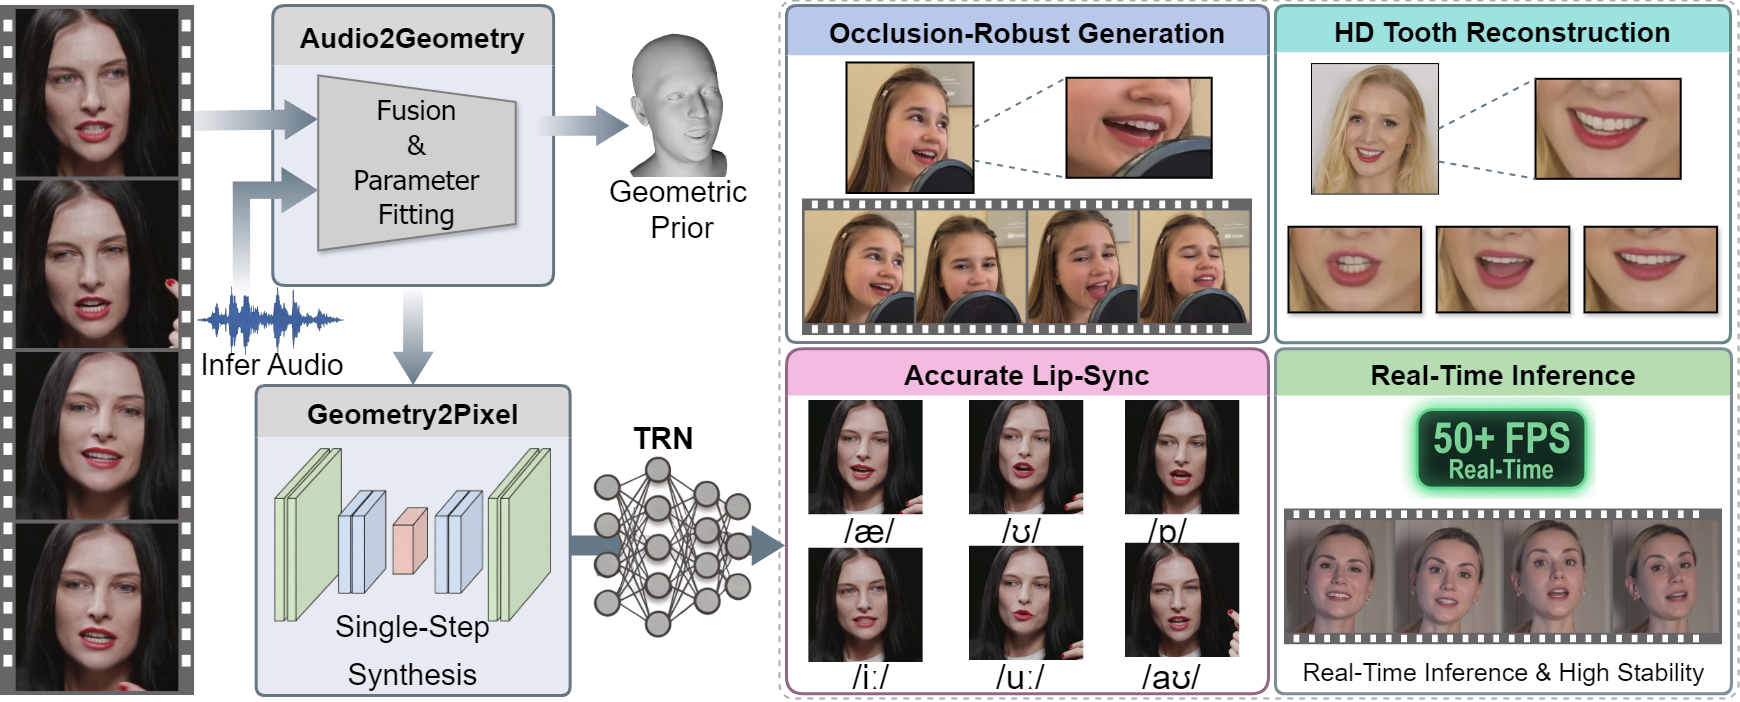
Audio-driven lip synchronization holds broad potential for live streaming, yet existing methods remain impractical due to three limitations: inpainting failures under foreground occlusions (e.g., microphones), inference latency incompatible with real-time constraints, and degraded tooth textures. Therefore, we present LiveDub, a real-time audio-driven lip synchronization system. To address these three challenges, LiveDub incorporates three targeted designs: (1) an occlusion-aware reference selection strategy that provides perioral priors robust to foreground occluders; (2) a reference masking strategy with a pixel-space tooth refinement network to eliminate shortcut artifacts and restore dental details; and (3) UNet3DMamba, a 3D hybrid backbone replacing quadratic attention with linear-complexity state-space modeling for real-time throughput with temporal consistency. LiveDub achieves 50 FPS on a single RTX 4090. Extensive experiments demonstrate significant improvements over state-of-the-art methods, making LiveDub the first framework to simultaneously deliver occlusion robustness, high-quality tooth synthesis, and real-time inference.
Results
Frontal videos with high-fidelity tooth synthesis
Videos with foreground occlusions (e.g., microphones)
Driving a target video with a mismatched audio source